Try it in a minute
A self-contained demo that shows what humpyard does, with no API keys and no network. It starts a local mock provider and a humpyard gateway, sends the same 11 requests two ways, and compares the cost from the gateway's own ledger.
Run it
You need python3, jq and a humpyard binary (from the
releases, or cargo build --release):
git clone https://github.com/gschaetz/humpyard && cd humpyard
HUMPYARD=/path/to/humpyard examples/demo/run.sh
It takes about ten seconds. Set DEMO_PACE=1 to have it type the commands and pause, as in the
recording above.
What it shows
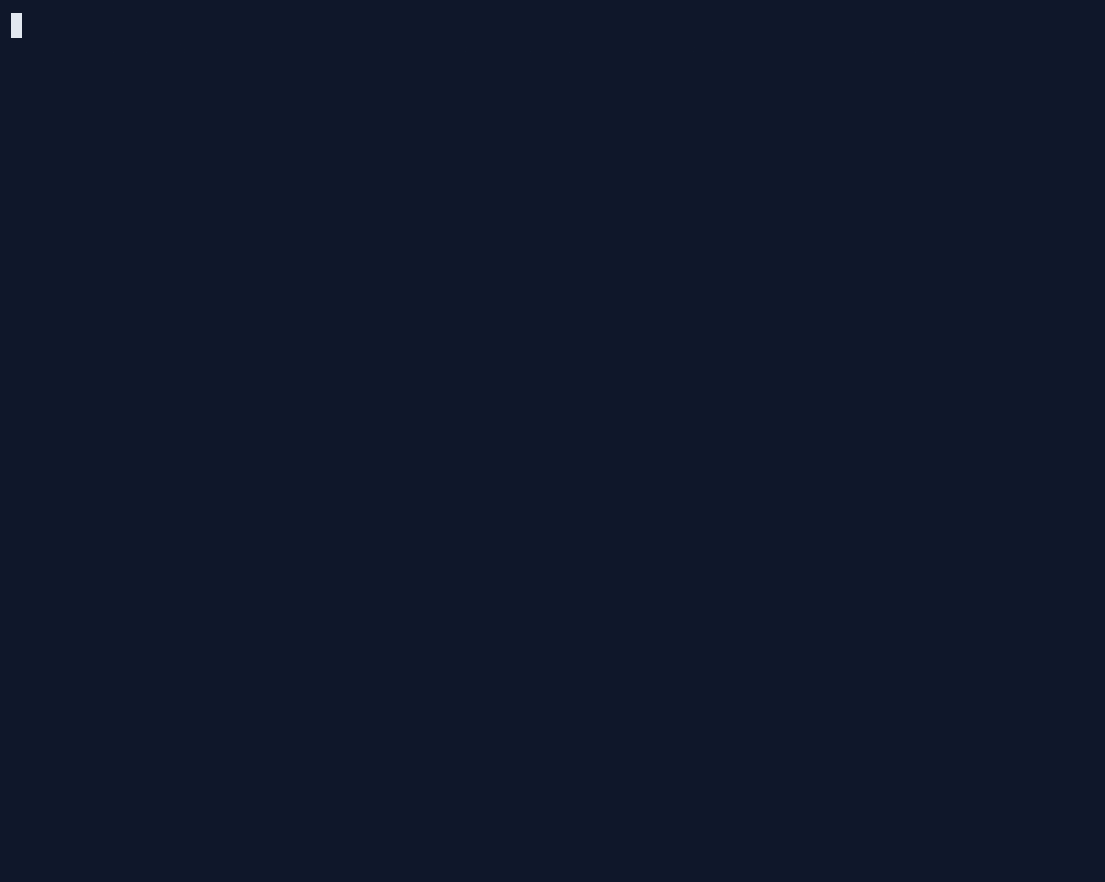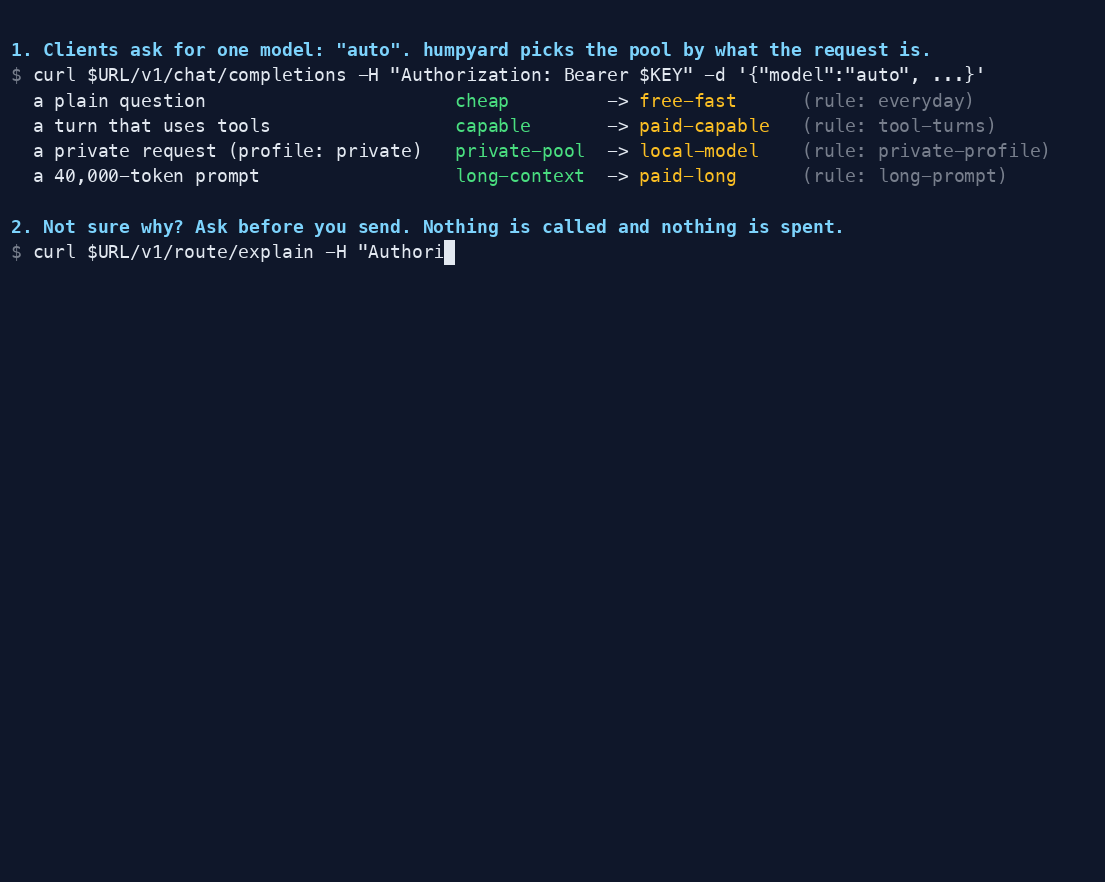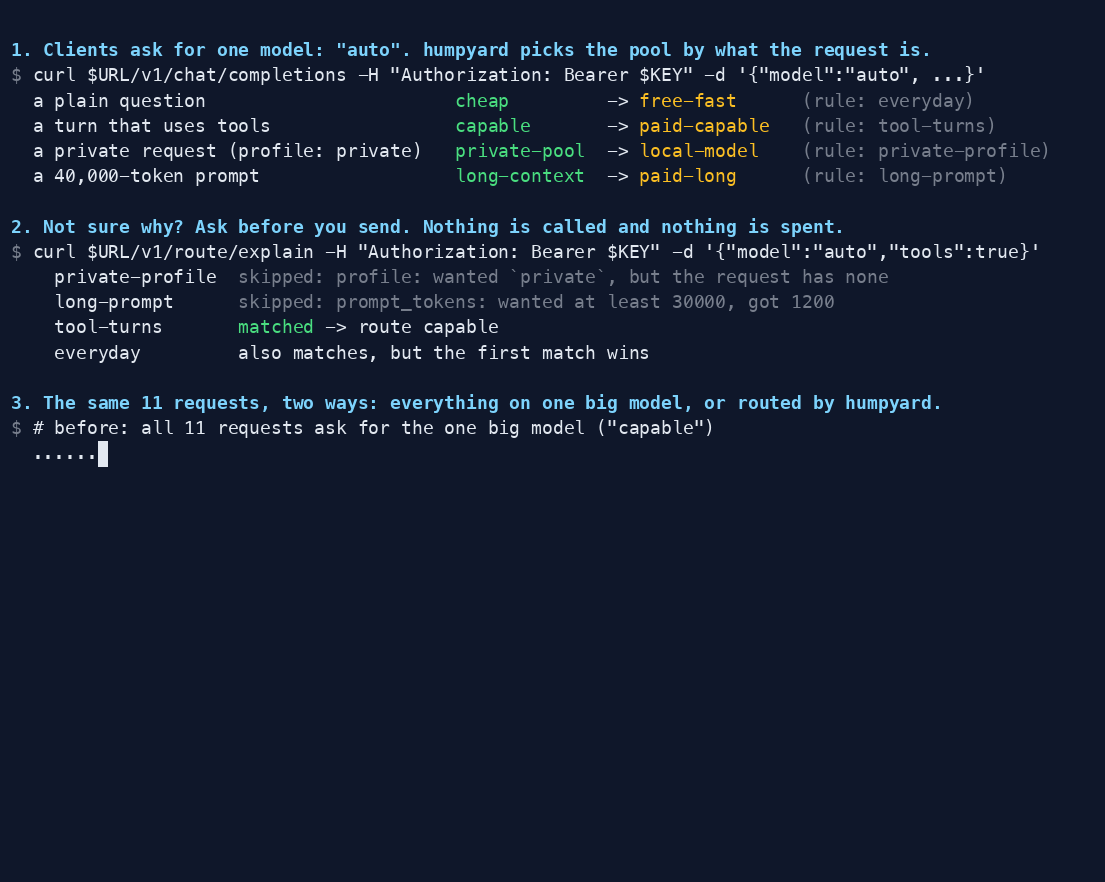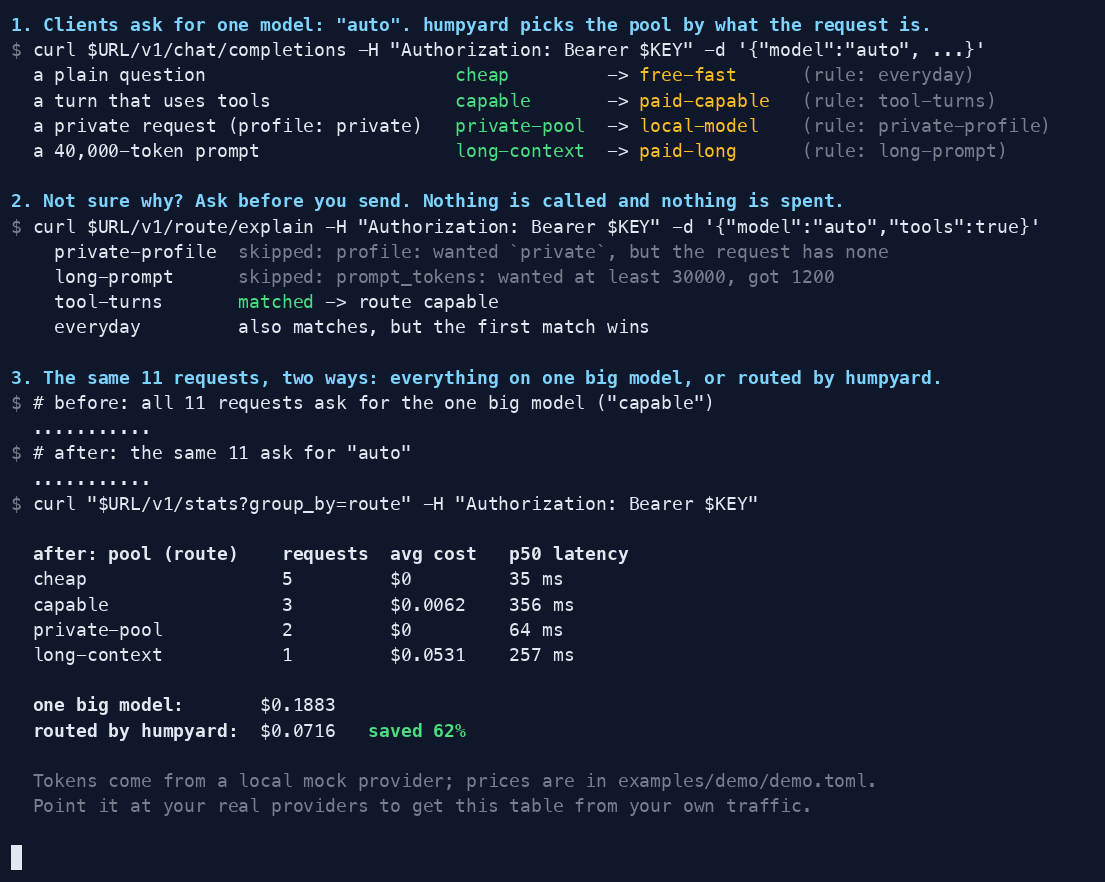
- One model name, different pools. Clients ask for
auto. A plain question goes to the free pool, a turn that uses tools goes to a stronger model, a request marked private stays on local hardware, and a 40,000-token prompt goes to a long-context model. The response headers (x-humpyard-route,-target,-rule) say which and why. See Selecting the route. - Asking before sending.
POST /v1/route/explainruns the same decision without calling a provider or spending anything, and lists every rule with why it matched or was skipped. - The cost. The same 11 requests are sent twice: once all to one big model, once as
auto.GET /v1/statsreports what each pool cost, and the two totals are compared. See Statistics.
What it does not show
The tokens come from a mock provider, not real models, so the answers are canned and the
latencies are made up. The prices are the ones in
examples/demo/demo.toml;
the percentage saved depends entirely on that traffic mix and those prices. What is real is the
gateway: the routing rules, the decisions, the ledger and the cost arithmetic. Point the same
config at your real providers and the same table comes from your own traffic.